Residual RL
Can a better action representation help an RL policy learn from fewer samples?
This is a RL class project with Xiangyun Meng and Mohit Shridhar.
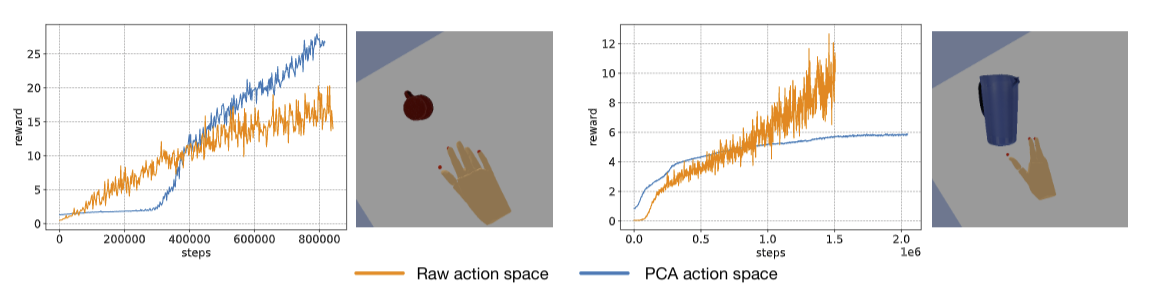
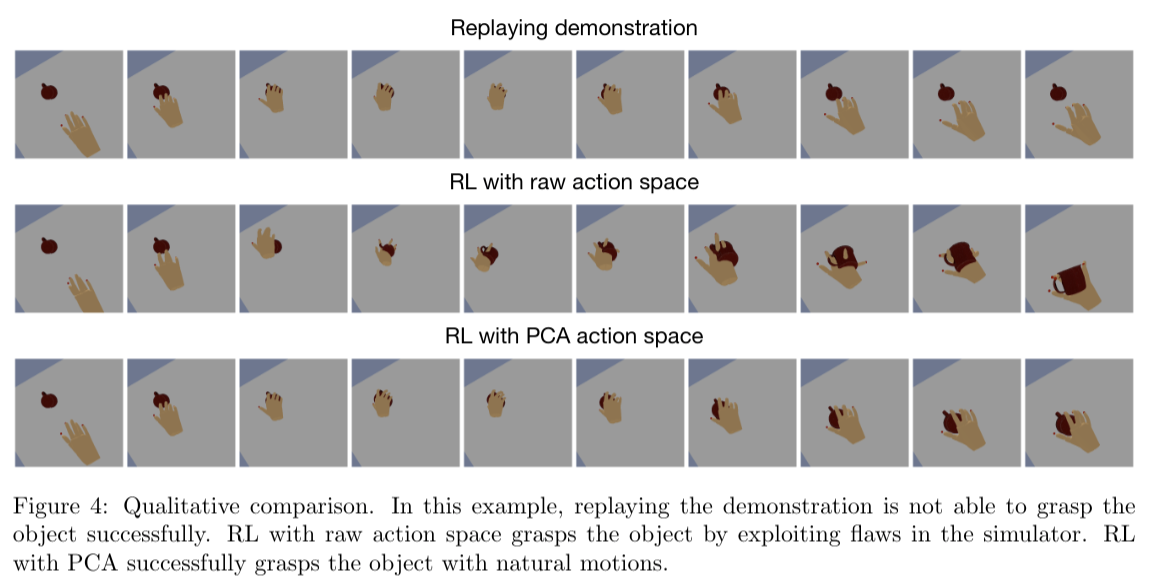
We explored whether residual reinforcement learning could refine human demonstrations in simulation. Reducing the action space with principal component analysis (PCA) preserved useful behavior from the demonstrations while helping the policy learn smoother trajectory refinements from fewer samples.
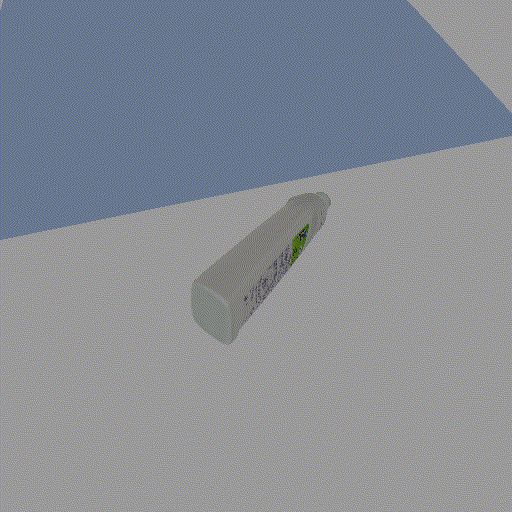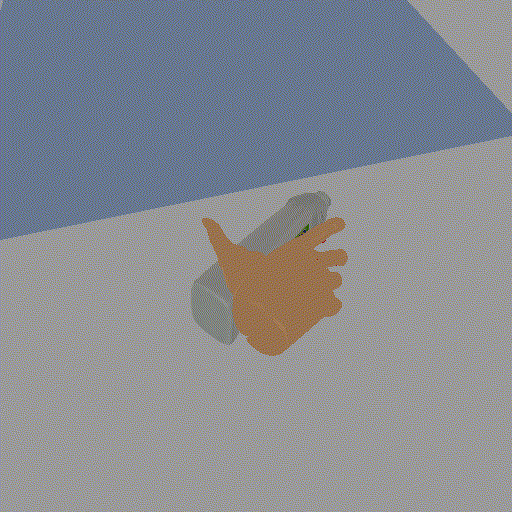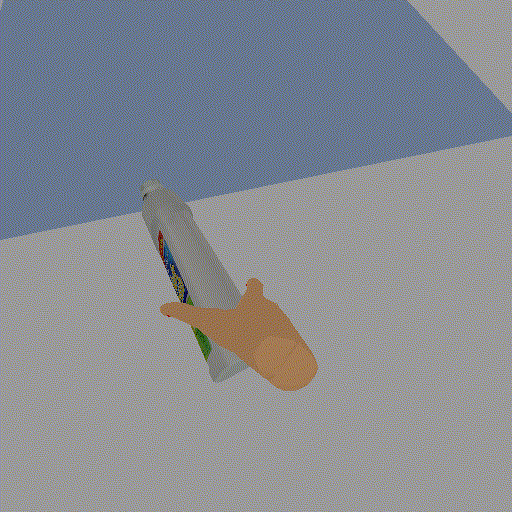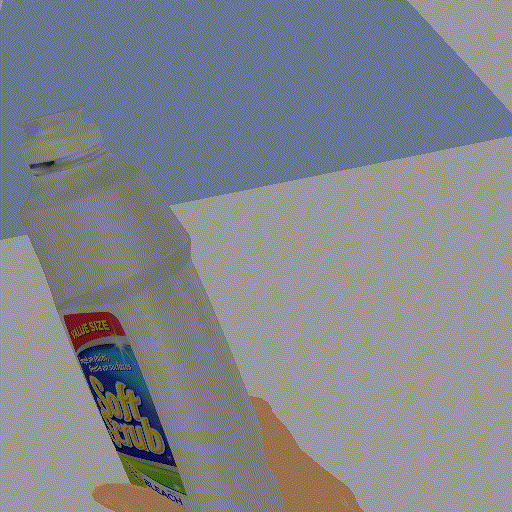
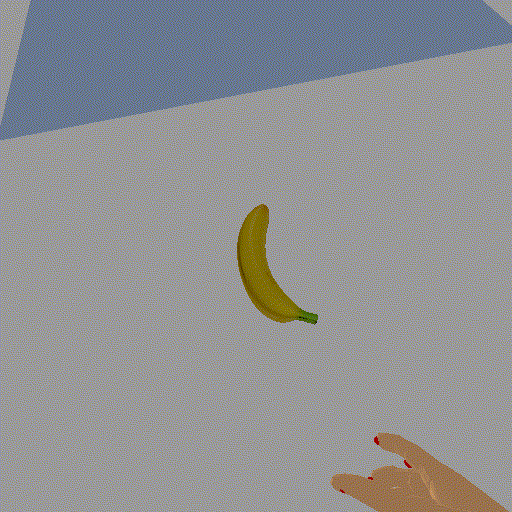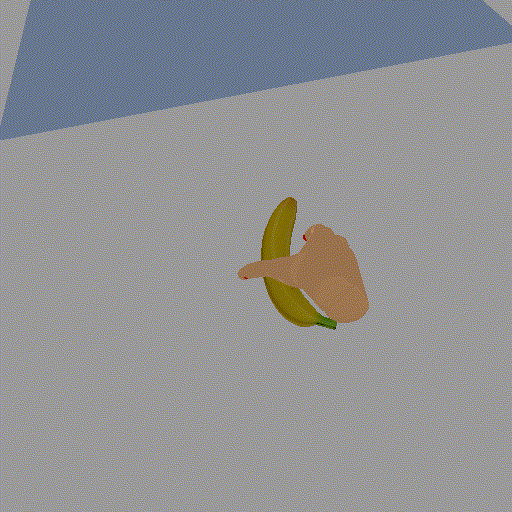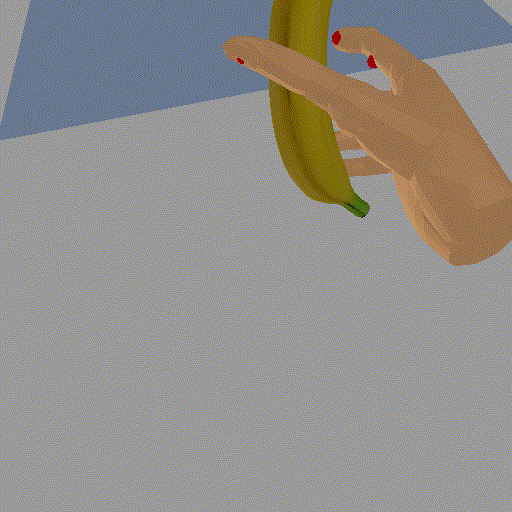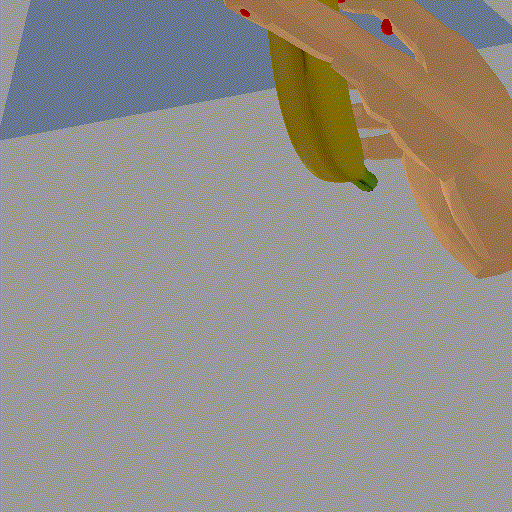
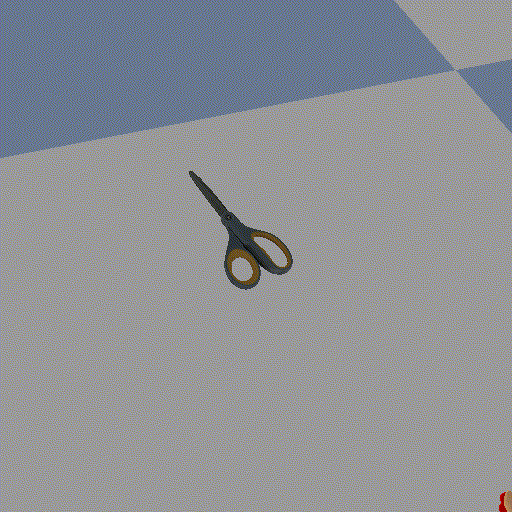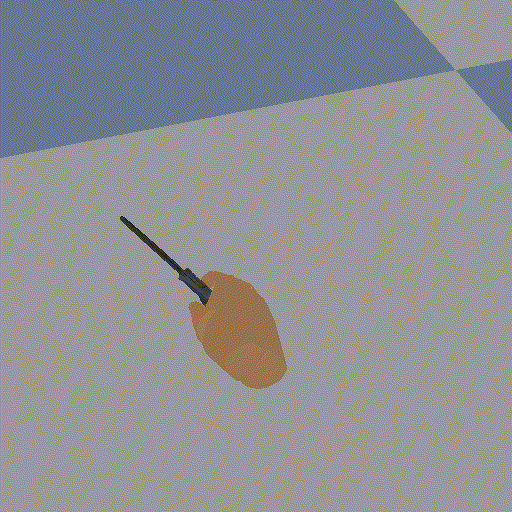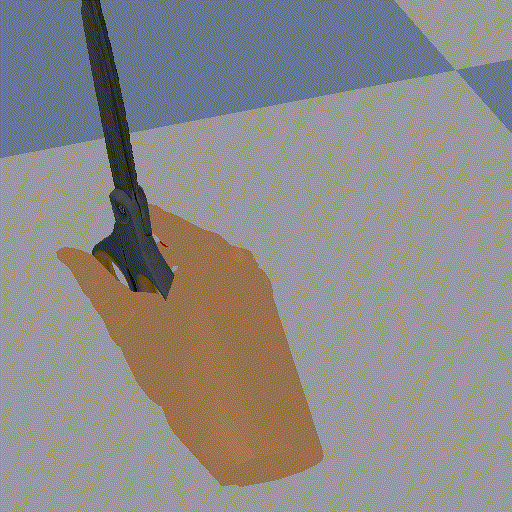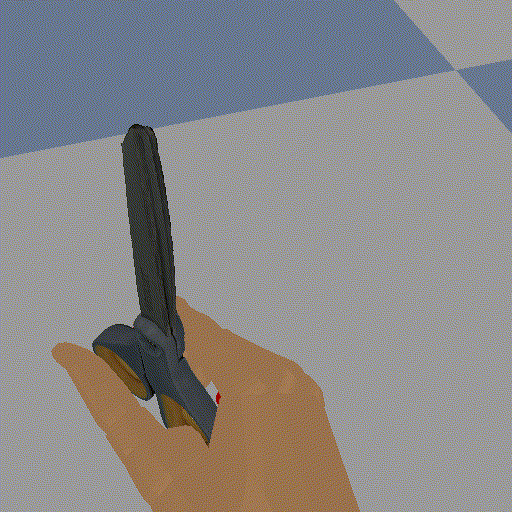
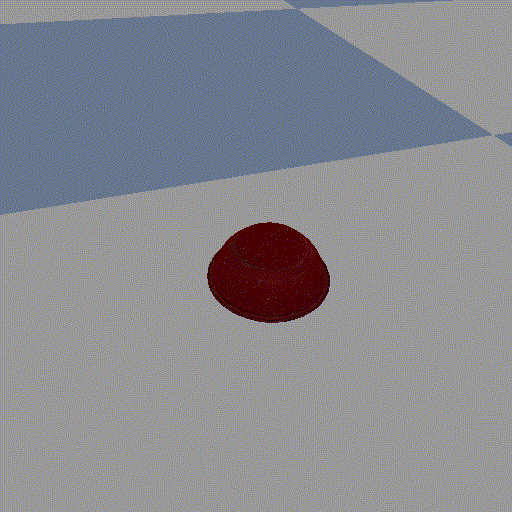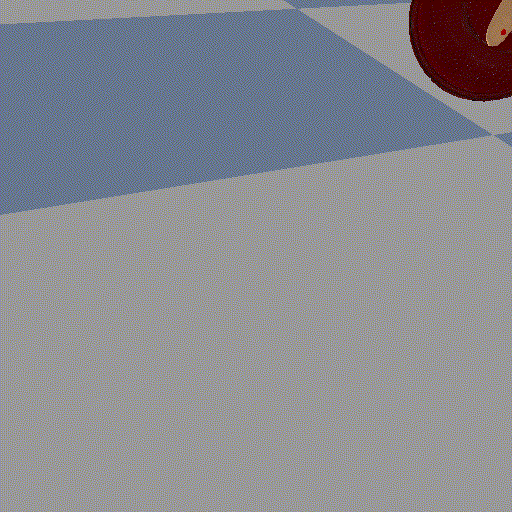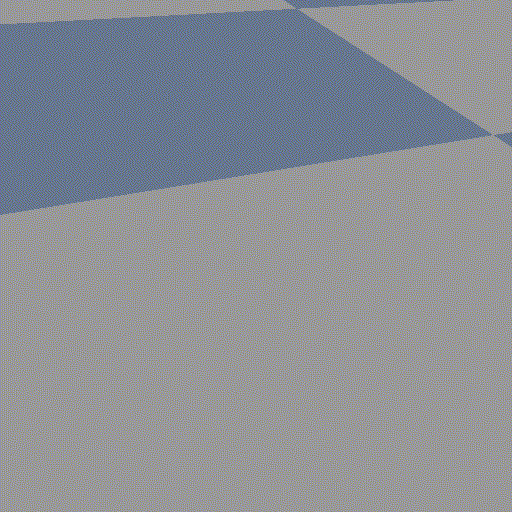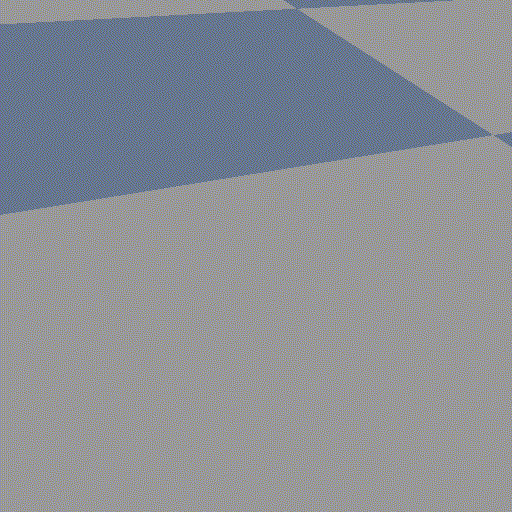
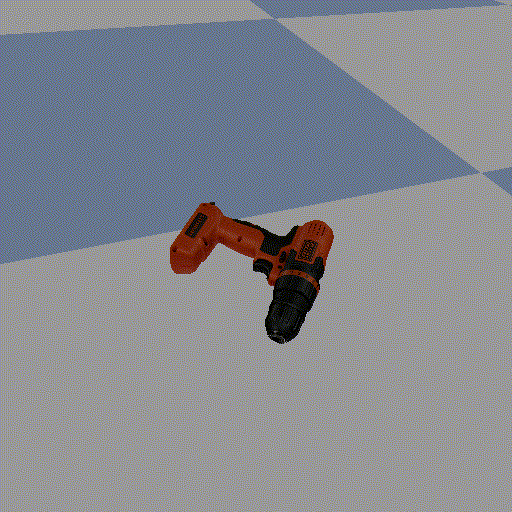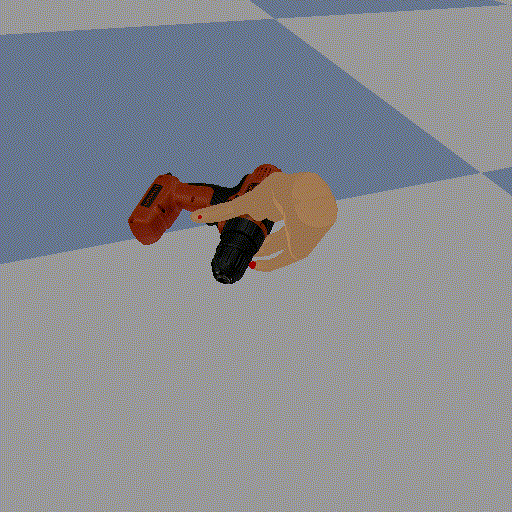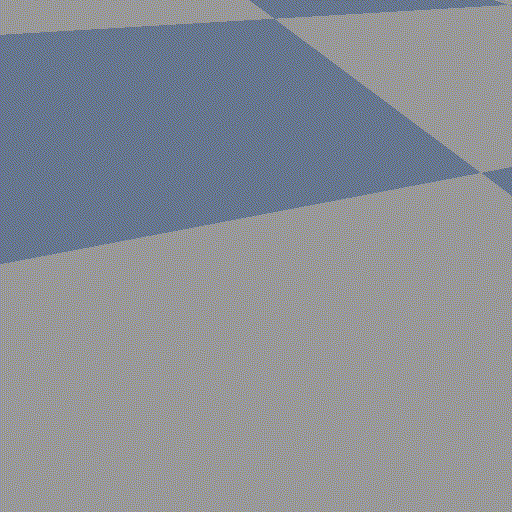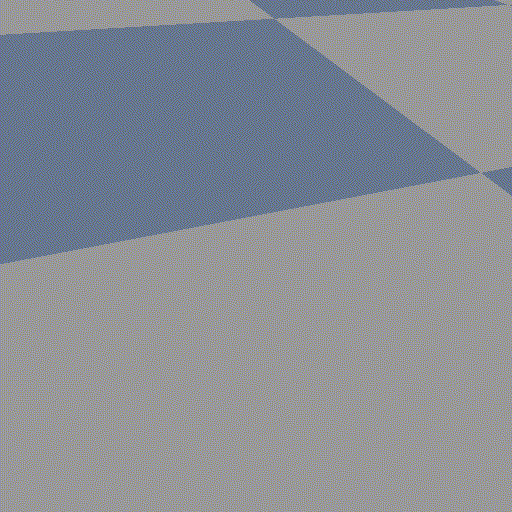
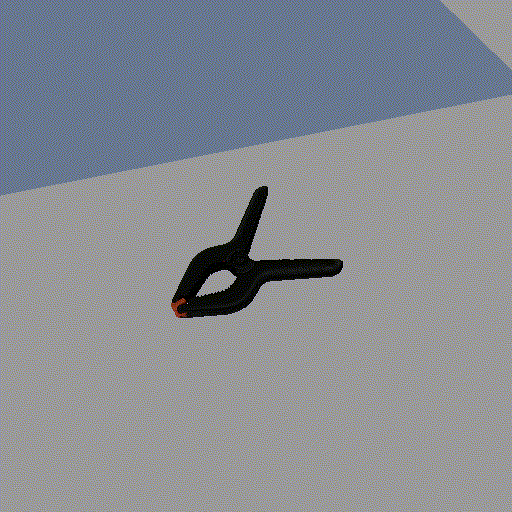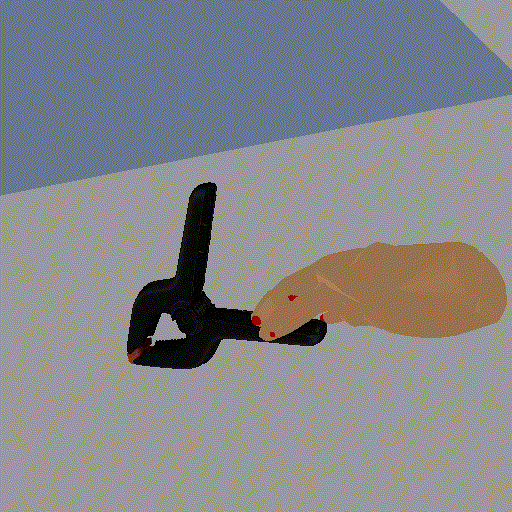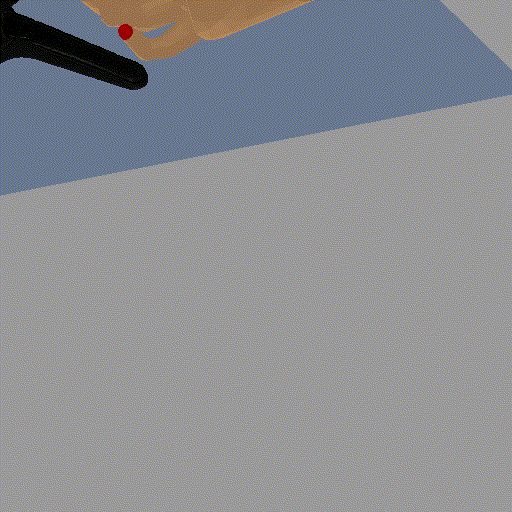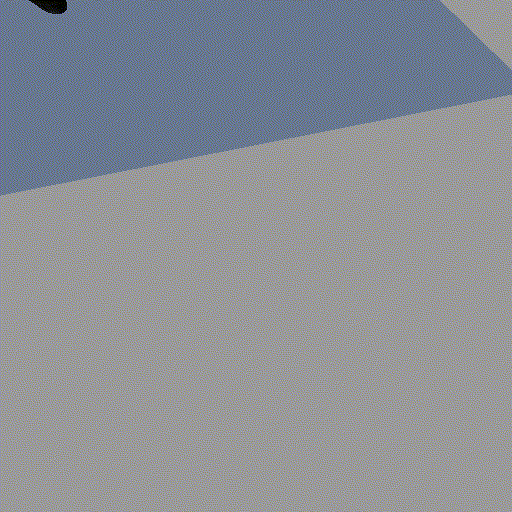
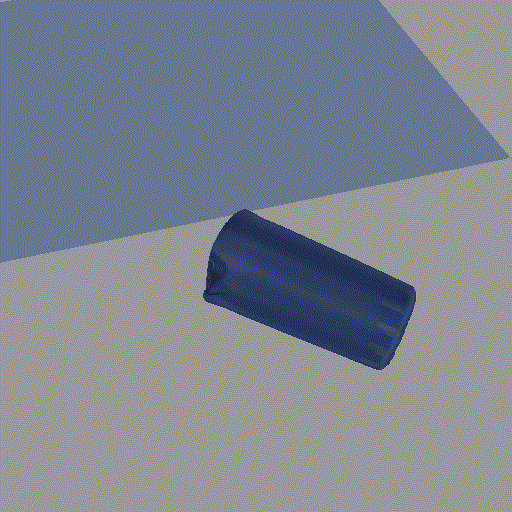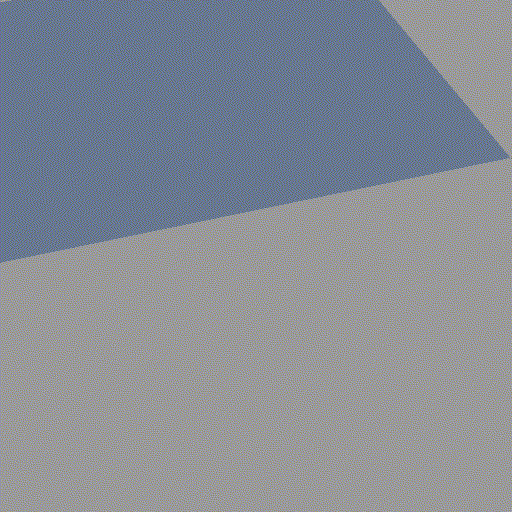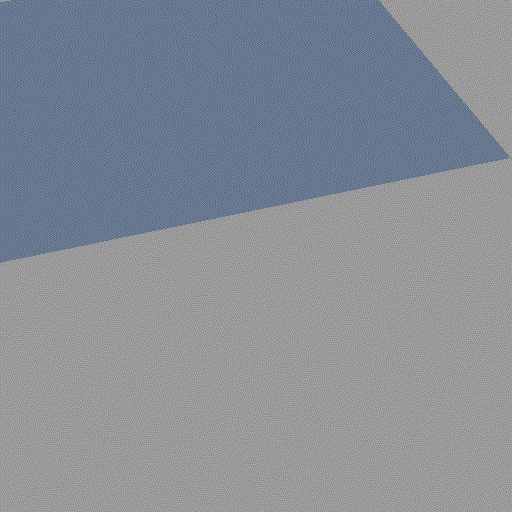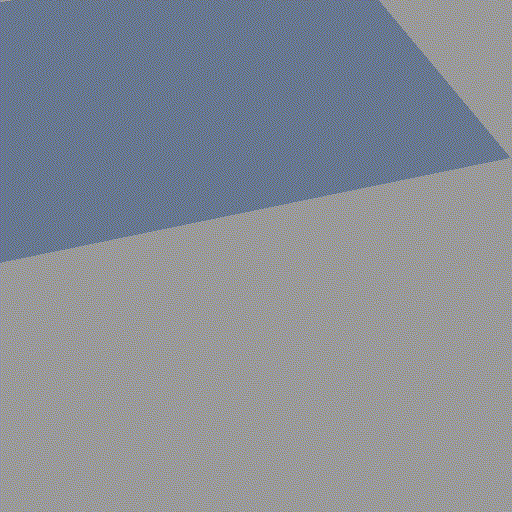
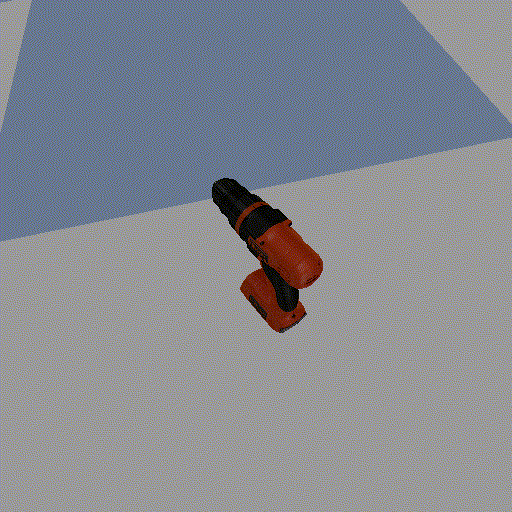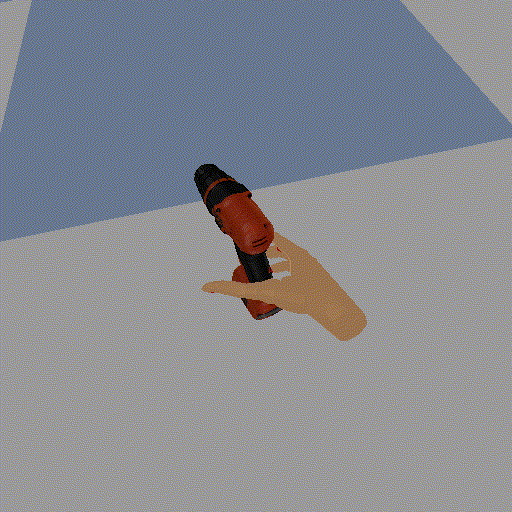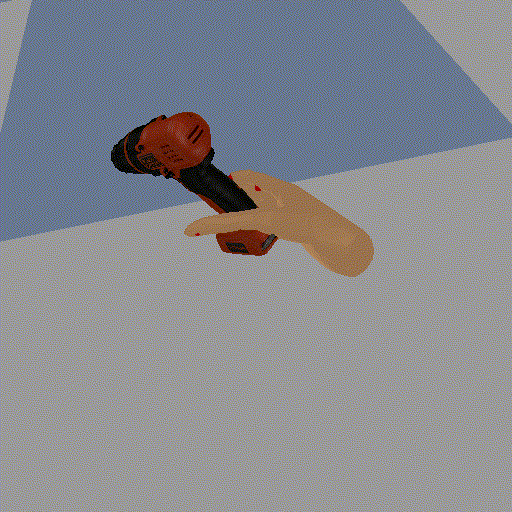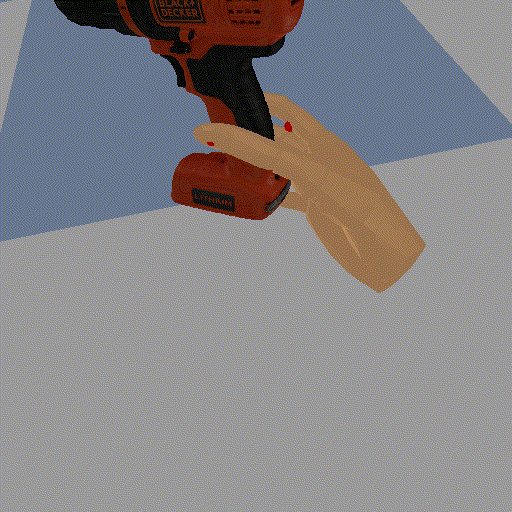
Grasping trajectories refined with residual RL succeeded where replaying human demonstrations failed because of tracking and inverse kinematics errors.